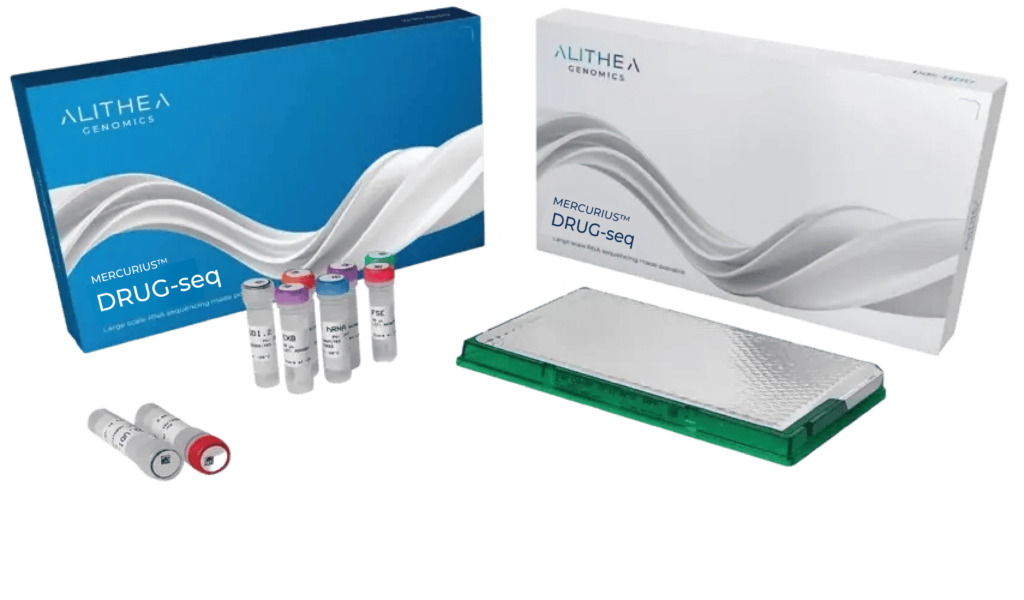
MERCURIUS™
DRUG-seq kits
for high-throughput transcriptomics
Extraction-free, plate-based RNA-seq library preparation for compound screening, mechanism-of-action studies, toxicity profiling, dose-response experiments, and AI-ready perturbation datasets.
Want to evaluate data first?
Explore performance plots and sample datasets →
Ideal for screening projects
No RNA extraction, no material loss
Pre-amplification-free protocol
One-day library prep workflow
Product Overview
MERCURIUS™ DRUG-seq is an extraction-free DRUG-seq kit for drug discovery teams that need transcriptome-wide gene expression readouts at a screening scale.
Designed for ultra-high-throughput detection of protein-coding transcripts in 2D cell lines and primary cells without expensive, time-consuming RNA extraction. Ideal for screening studies with larger cohorts, more conditions, or more timepoints than possible to realistically assess with standard bulk RNA-seq methods.
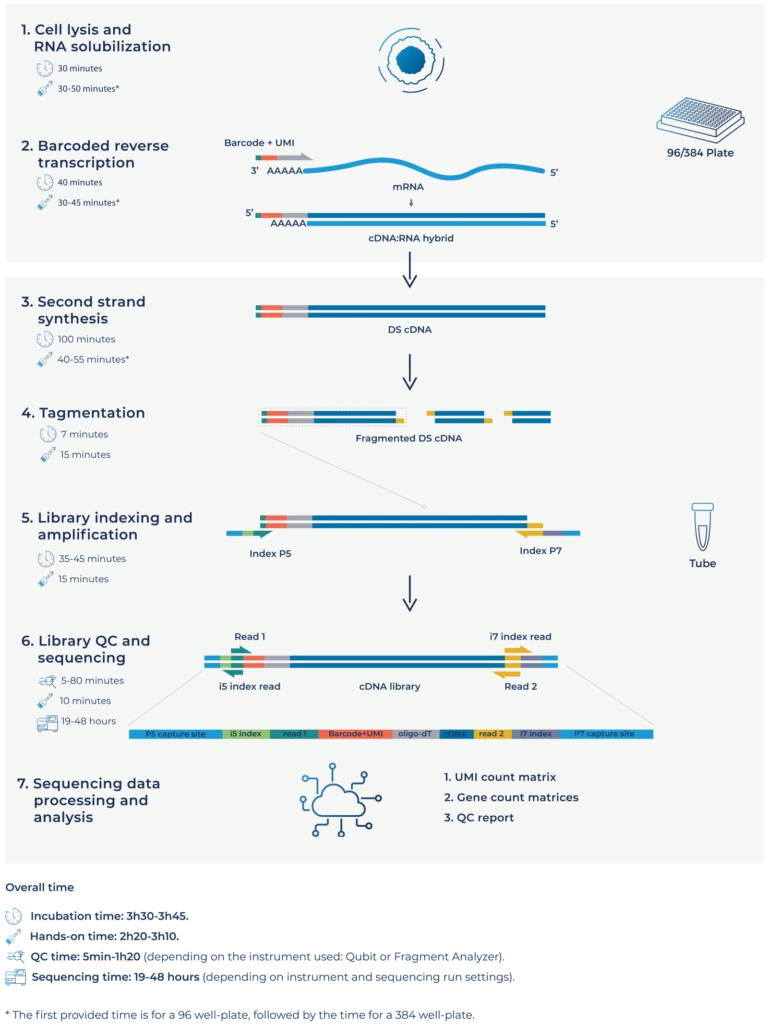
By combining in-well cell lysis, early barcoding, and multiplexing of up to 96, 384, or 1536* samples in a single tube, MERCURIUS™ DRUG-seq makes high-throughput RNA-seq practical for large compound libraries, multi-dose studies, time-course experiments, and whole-transcriptome CRISPR perturbation screens. The workflow supports compound screening, hit triage, mechanism-of-action studies, toxicity profiling, dose-response experiments, and AI-ready perturbation dataset generation.
at 1M reads/sample
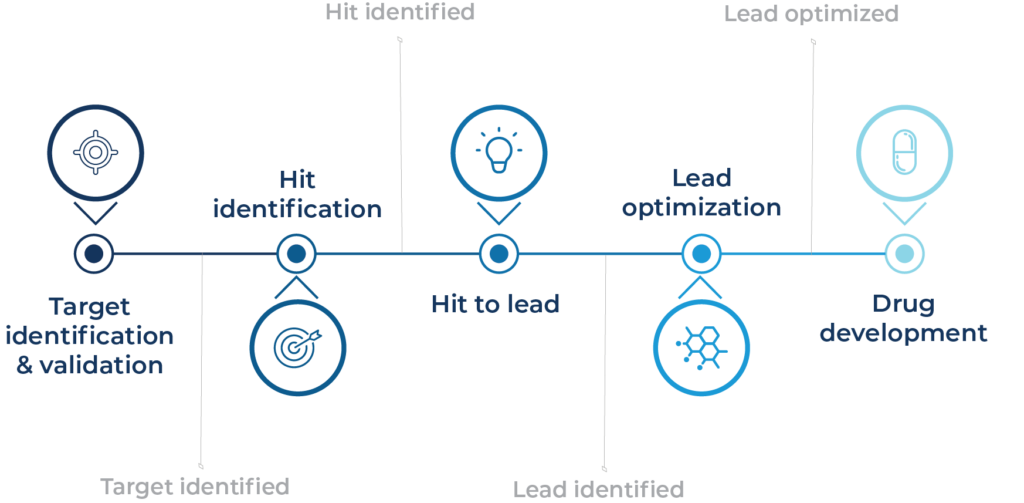
Applications of DRUG-seq in the drug discovery pipeline
- Hit triage after phenotypic or target-based screens
Prioritize compounds based on transcriptome-wide biological response, not only potency or viability. - Mechanism-of-action and target engagement studies
Compare transcriptional signatures across compounds, doses, controls, and genetic perturbations. - Early toxicity and stress-response profiling
Detect pathway-level safety signals earlier in the discovery funnel. - Dose-response and time-course transcriptomics
Map compound effects across concentration and exposure windows. - Compound clustering and similarity analysis
Group compounds by transcriptional response to support MoA inference and follow-up assay design. - AI-ready perturbation datasets
Generate structured gene expression matrices for predictive modeling, compound-response analysis, and multimodal screening workflows.
Why use DRUG-seq for large compound screening?
Scroll right
Method
Best fit
Considerations for large-scale screening

Standard bulk RNA-seq

Targeted gene expression panels

L1000 / landmark-gene profiling

Cell Painting
MERCURIUS™
DRUG-seq
Performance data
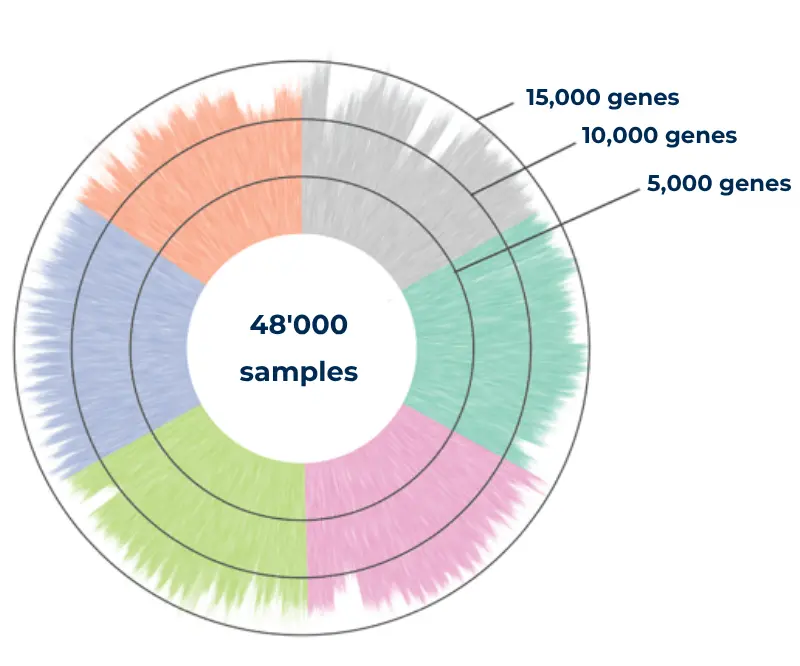
Detects 13k+ genes at 1M reads/sample
Distribution of the number of detected genes across 48,000 samples in 125 × 384-well MERCURIUS™ DRUG-seq plates from six different frozen cell lines. The library was sequenced at an average of 1 million reads per sample on an Illumina NovaSeq 6000.
51
Compounds
6
Cell lines
13k
Genes/sample
1M reads/sample
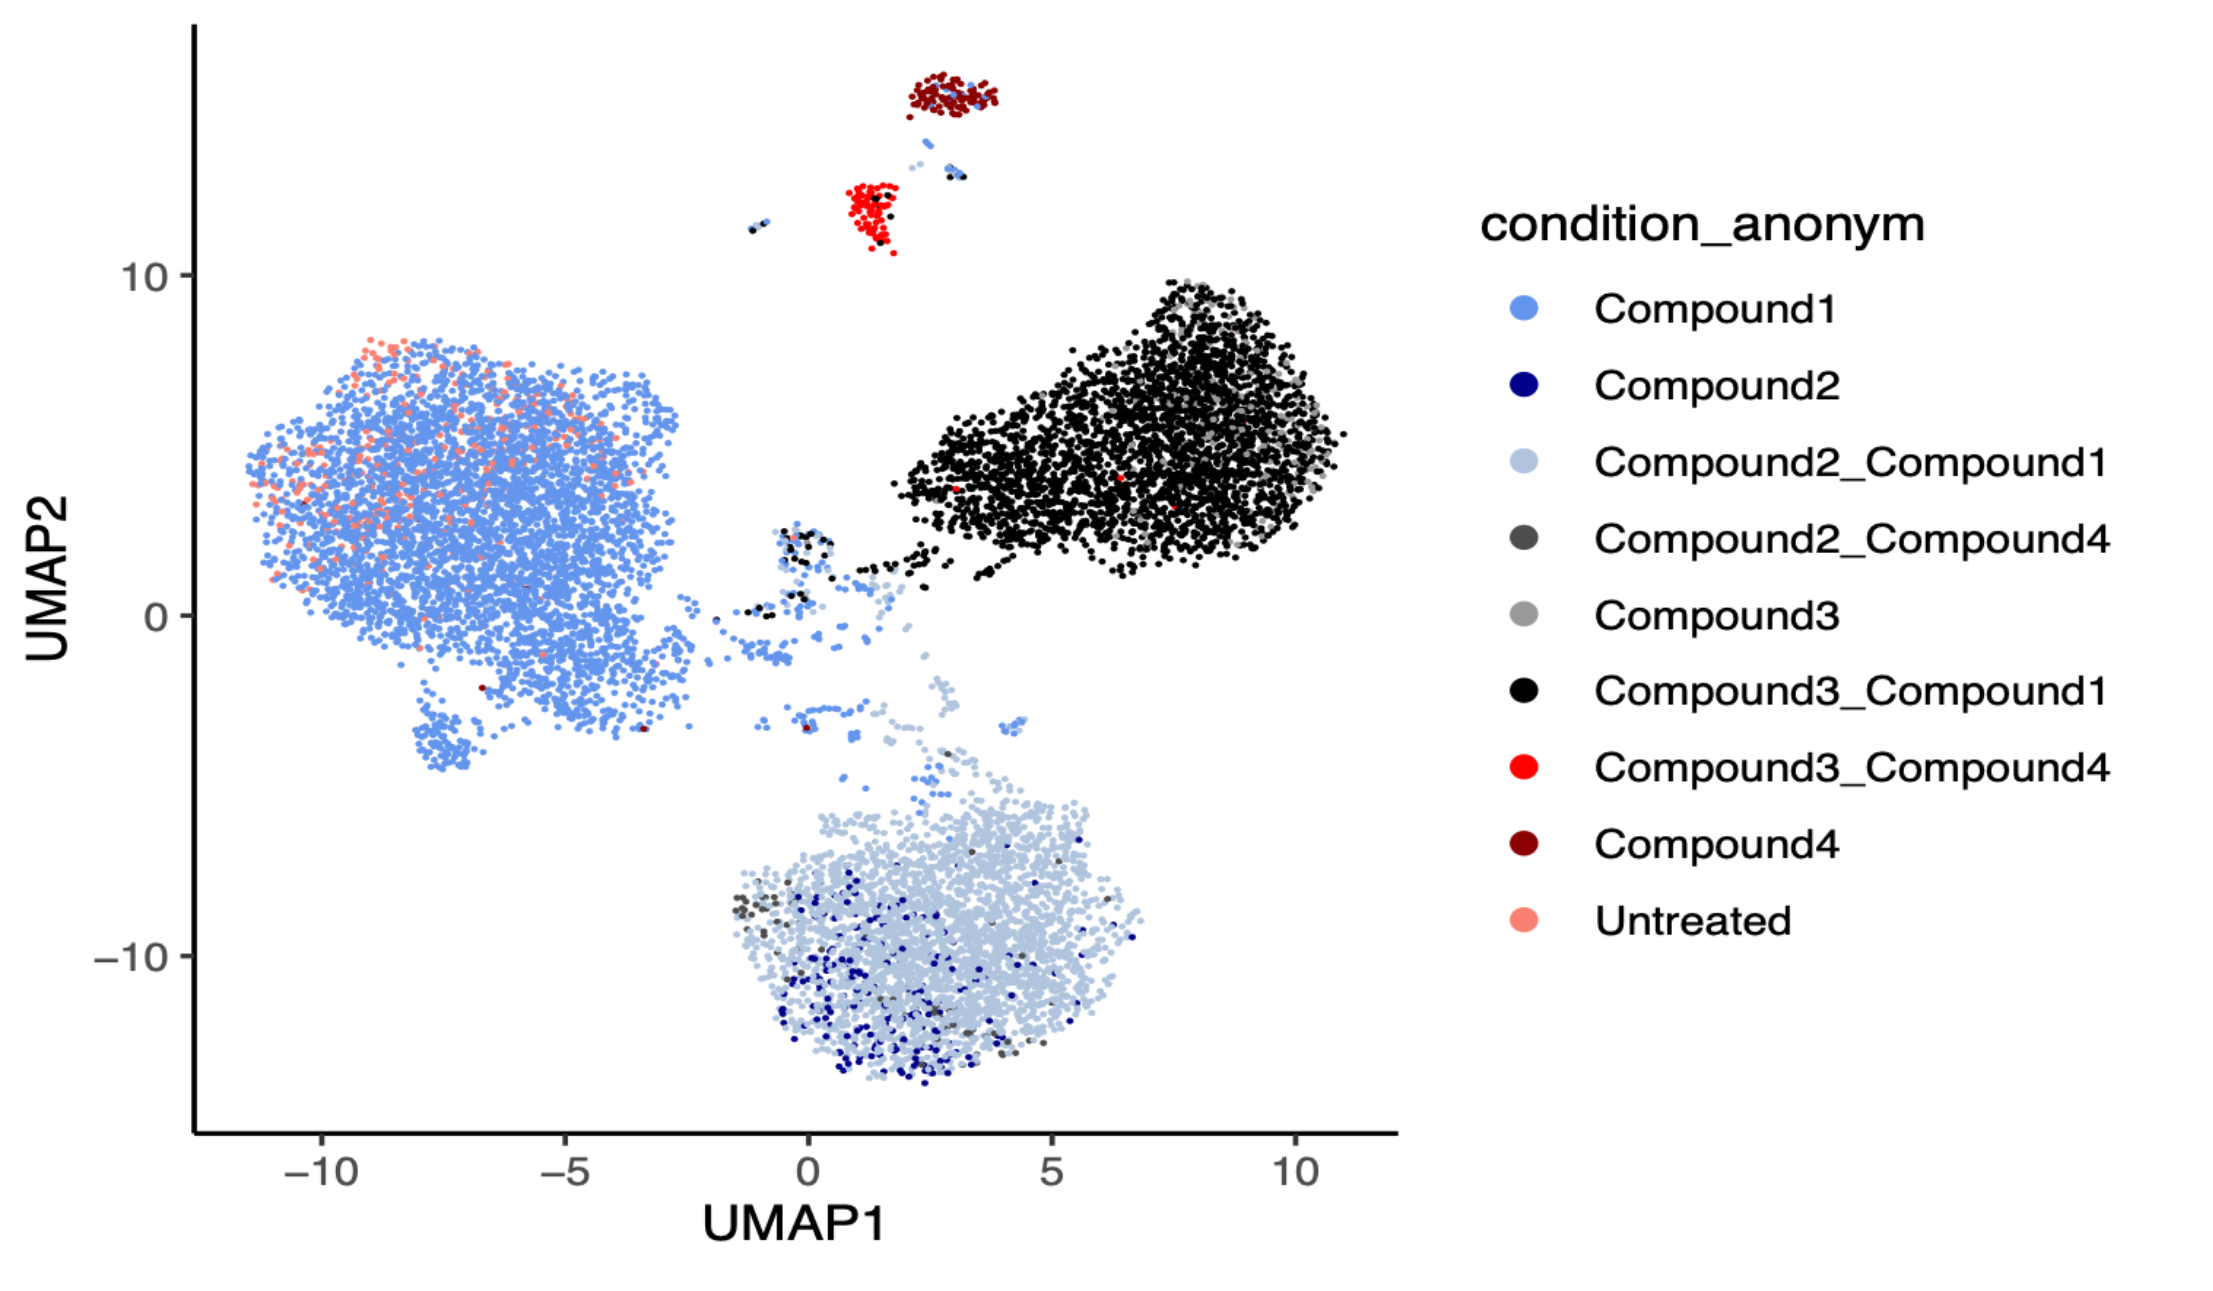
Enables accurate compound clustering and co-clustering analysis based on unbiased gene expression
UMAP projection of transcriptional profiles from cells treated with four compounds individually and in combination, alongside untreated controls. Each point represents a single sample, coloured by treatment condition. Samples cluster by transcriptional similarity, revealing that single-compound treatments and combination treatments occupy distinct regions of transcriptional space.
Sample Datasets
AGDS_DS384_Huh7_TGFb_SB_MOA
Dataset details
AGDS_DS1536_HEPG2_MOA
Dataset details
- 800 HepG2 cells were plated per well across two 1536-well plates. A panel of 33 compounds with known mechanisms of action was tested across eight compound-specific concentrations, with five replicates per condition. Cells were exposed to compounds for 24 hours.
- Following treatment, CellTiter-Blue® was used to measure cell viability directly on the same plates. This provided an orthogonal phenotypic readout that could be compared with the transcriptomic response.
- After the viability assay, cells were prepared for extraction-free DRUG-seq processing. Each of the 1,536 samples was uniquely barcoded during reverse transcription, and all samples were subsequently pooled into a single tube for library preparation.
Product documentation
Publications
- 3' DRUG-seq, DRUG-seq
Rodrigues Sousa, E., de Brot, S., Zoni, E. et al.
- DRUG-seq, Spheroid DRUG-seq
Anstett, V.; Heinzelmann, E.; Piraino, F.; Roch, A.; Chrisnandy, A.; Norkin, M.; Garnier, V.; Homicsko, K.; Hoehnel-Ka, S.; Brandenberg, N.
Application
Equipment compatibility
Species compatibility
Available formats
Shipping conditions
Storage conditions
Validated Cell Lines
Liver / Hepatic Models
| HepaRG | Liver |
| HepG2 | Liver (HCC) |
| Huh7 | Liver (HCC) |
| Hep3B | Liver (HCC) |
| PHH (Primary Human Hepatocytes) | Primary liver |
| NCI-H295R | Adrenal/liver metabolism |
Cancer Cells
| MCF7 | Breast cancer |
| A549 | Lung carcinoma |
| H358 | Lung cancer |
| NCI-H1563 / H1048 | Lung cancer |
| DLD-1 | Colorectal cancer |
| SW837 | Colorectal cancer |
| HCT116 | Colorectal cancer |
| LS180 | Colorectal cancer |
| COLO201 | Colorectal cancer |
| C2BBe / C2BBe1 | Colorectal |
| GP5d | Colorectal |
| U2OS | Osteosarcoma |
| A172 | Glioblastoma |
| PSN-1 | Pancreatic cancer |
| AsPC-1 | Pancreatic cancer |
| SU.86.86 | Pancreatic cancer |
| A375 | Melanoma |
| HaCaT | Keratinocyte |
| UMUC3 | Bladder cancer |
| 5637 | Bladder cancer |
| HT1197 | Bladder cancer |
| Cal29 | Bladder cancer |
| UBLC1 | Bladder cancer |
Blood / Immune Cells
| PBMC | Primary blood |
| Jurkat | T-cell leukemia |
| Raji | B-cell lymphoma |
| THP-1 | Monocyte |
| U937 | Monocyte |
| MV-4-11 | AML |
| MOLM13 | AML |
| HL60 | Leukemia |
| MM1S | Myeloma |
| KMS12BM | Myeloma |
| CD4+ / CD8+ T cells | Primary immune |
| Tregs / TILs | Immune subsets |
| CD3 T cells | Immune |
Stem Cells / iPSC-Derived Models
| iPSC | Pluripotent |
| iPSC-derived neurons | Neural |
| iPSC-derived cardiomyocytes | Cardiac |
| iPSC-derived cortical neurons | Neural |
| iPSC-derived organoids | Various |
Neural / Glial Models
| HMC3 | Microglia |
| Luhmes | Dopaminergic neuron |
| IMR90 | Fibroblast (used in brain spheres) |
| iCell GlutaNeurons | Neurons |
| Astrocytes (human/mouse/rat) | Glial |
Fibroblast
| NHDF | Dermal fibroblast |
| MEF | Mouse embryonic fibroblasts |
Epithelial
| HEK293 / HEK293T | Kidney (transformed) |
| ARPE-19 | Retinal epithelium |
| NHEK | Keratinocytes |
| Lung epithelial | Epithelial |
| RPTEC/TERT1 | Kidney (proximal tubule) |
| T84 | Colon epithelium |
Adipose
| Human adipocytes | Primary |
| Brown adipocytes | Metabolic |
| Visceral adipocytes | Primary |
| Mouse/canine adipose | Animal |
How many pools can I prepare with one kit?
Each DRUG-seq or BRB-seq kit contains reagents (including four pairs of Unique Dual Indexing adapters) sufficient for the complete library preparation process for four different pools.
To note, the total number of RNA samples that can be processed with one kit does not exceed the kit specifications; for instance, a 96-sample kit can be used to prepare up to 96 samples distributed across up to four different libraries.
What are the input requirements for the cellular material?
The DRUG-seq technology can be used to generate high-quality sequencing data from 2000 – 50000 mammalian cells per well. Notably, the kit can be used to pool any number of samples up to the capacity of the provided plate (96 or 384) with two considerations:
• The total cell number per pool should be at least 80000.
• Pooling less than eight samples may result in low-complexity reads during sequencing, decreasing the overall sequencing quality.
How does the bioinformatic analysis of DRUG-seq differ as compared to standard RNA-seq?
The only difference between DRUG-seq and standard RNA-seq data analysis is the demultiplexing step, which is used to assign sequencing reads to their sample of origin based on the DRUG-seq barcode sequence.
For a thorough description of DRUG-seq data processing, please refer to the DRUG-seq kit data analysis user guide.
How do I identify which barcode set I should use to demultiplex my data?
The barcode set for your kit is conveniently located on the kit label. Please refer to the label for accurate identification.
For optimal compatibility, ensure that you use the appropriate plate format (e.g., for kits designed for 96 reactions, the 96 well-plate format should be used). This ensures accurate and efficient processing of your samples. If you have any further questions or concerns, please contact our support team for assistance by email or using our live chat tool.
How is DRUG-seq used in drug discovery?
DRUG-seq is used to generate transcriptome-wide gene expression profiles after compound, genetic, or other perturbations. In drug discovery pipelines, these profiles can support hit triage, mechanism-of-action studies, toxicity profiling, dose-response analysis, compound clustering, and AI-ready perturbation dataset generation. Read more.
When should I use DRUG-seq in a compound screening workflow?
DRUG-seq is most useful when a screening team needs richer biological context than single-endpoint assays can provide, but standard RNA-seq is too costly or slow for the number of compounds, doses, time points, or replicates being tested.
Can DRUG-seq help identify mechanism of action?
Yes. DRUG-seq generates transcriptional signatures that can be compared across compounds, controls, doses, and perturbations. Compounds with related mechanisms can show similar gene expression patterns, supporting MoA inference, pathway analysis, and follow-up assay selection.
Can DRUG-seq be used after Cell Painting or high-content imaging?
Yes. DRUG-seq can provide a molecular readout to complement morphological phenotypes from Cell Painting or other high-content imaging assays, helping connect cellular phenotypes to pathway-level transcriptional responses. Read more.
Is DRUG-seq suitable for AI-ready perturbation datasets?
Yes. DRUG-seq can generate structured gene expression matrices across many compounds, concentrations, cell models, and time points, making it useful for predictive modeling, compound similarity analysis, and perturbation-response datasets. In fact, DRUG-seq is an ideal method for generating foundational datasets for AI drug discovery. Read more.
What are the limitations of DRUG-seq?
DRUG-seq is optimized for scalable 3′ mRNA counting and gene-level expression profiling. It is not the best choice when the main goal is isoform discovery, fusion detection, alternative splicing, or full-length transcript analysis. For those applications, MERCURIUS™ Total DRUG-seq is a more appropriate method.
Ask your question:
Kit name
Catalog number
pairs
MERCURIUS™ DRUG-seq library prep kit (96 preps)
all eukaryotic species
MERCURIUS™ DRUG-seq library prep kit (4x96 preps)
all eukaryotic species
MERCURIUS™ DRUG-seq library prep kit (384 preps)
all eukaryotic species
MERCURIUS™ DRUG-seq library prep kit (4x384 preps)
all eukaryotic species
* Contact us to inquire about compatibility with other species.
** Find the list of validated cell lines here.
Accessories
Product
Number of Samples
MERCURIUS™ UDI Expansion module
MERCURIUS™ Cell Lysis Modules
MERCURIUS™ Cell Lysis Modules
MERCURIUS™ Standard Post-Pooling Preparation Module (4 libraries)
Ordering tip
Each kit includes 4 UDI pairs. Add the expansion module if you need more unique indexes (total 16 UDI pairs available).
Related Blog Posts
August 25, 2026
Toxicology has traditionally relied on apical observations in animal models with limited use of high-throughput transcriptomics and AI. Yet these single endpoints with limited predictive…
June 29, 2026
For the first time, 1536-well whole transcriptome profiling brings biologically rich readouts to primary screening and large-scale perturbation dataset generation. In this webinar, Alithea Genomics…
March 25, 2026
Biomarker discovery using gene expression signatures has transformed pharmaceutical discovery and development, from early hit triage and target validation to toxicology, dose optimization, and patient…
March 23, 2026
Next-generation AI models for drug discovery are only as powerful as the quality, size, and perturbation-richness of their training data. Yet no publicly available dataset…