MERCURIUS™
BRB-seq Kits
for cost-effective bulk
RNA-seq
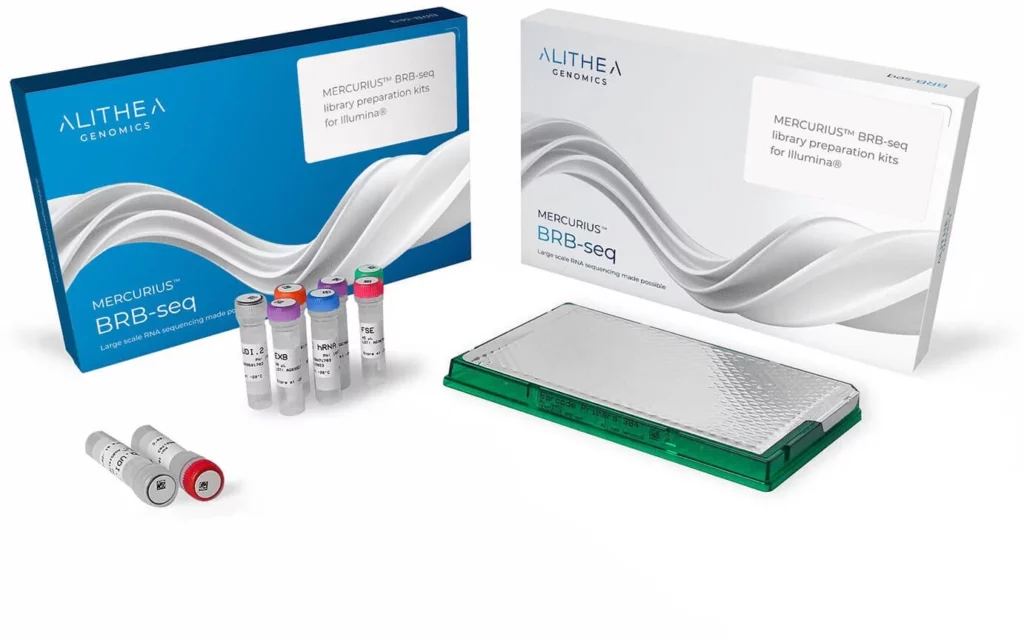
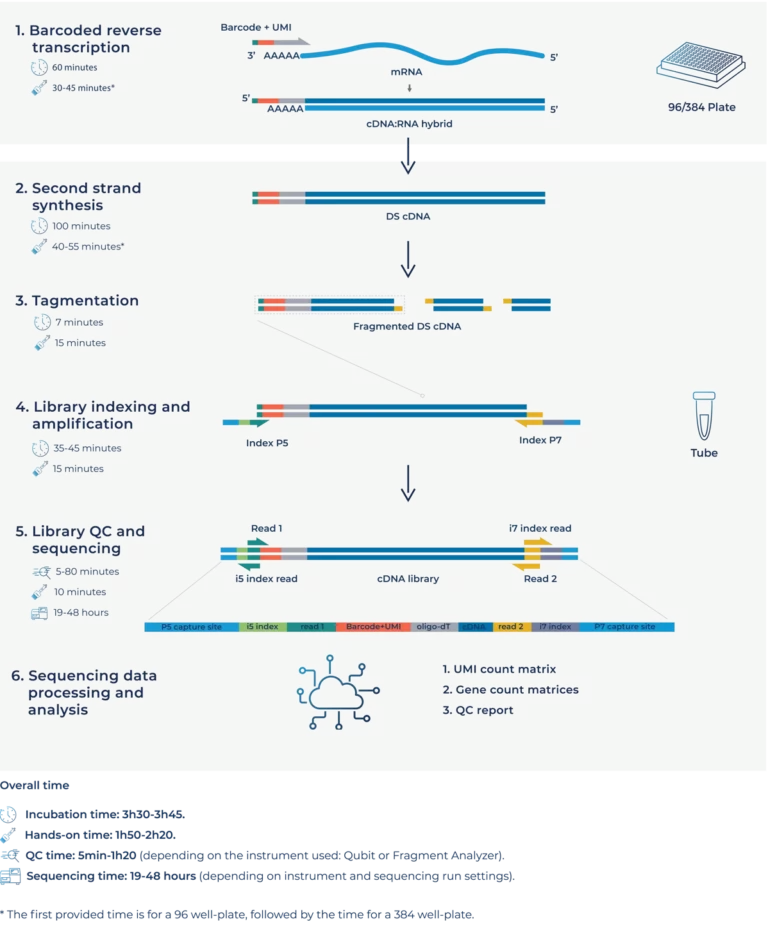
MERCURIUS™ BRB-seq is a bulk RNA-seq kit that enables scalable 3′ mRNA-seq from purified RNA, with early sample barcoding and multiplexing of up to 96 or 384 samples in a single tube.
Discover Sample Datasets
Mammals, Plants, Insects, Fish
Bulk RNA sequencing at scale
BRB-seq as a flexible solution
One-day library prep workflow
For a variety of sample types
Product Overview
MERCURIUS™ BRB-seq is a bulk RNA-seq kit for researchers who need cost-effective gene expression profiling across many purified RNA samples. The workflow is designed for academic labs, core facilities, and research teams running studies with larger cohorts, multiple conditions, time points, tissues, species, or perturbations.
By combining early sample barcoding, unique molecular identifiers, and sample pooling, MERCURIUS™ BRB-seq reduces workflow complexity and makes scalable 3′ mRNA-seq practical for differential gene expression analysis, transcriptome profiling, and large experimental designs.
1.5M reads/sample
Applications
- Differential gene expression studies
Compare expression profiles across experimental conditions, treatments, genotypes, or time points. - Large-cohort RNA-seq projects
Profile purified RNA from tens to hundreds of samples using a scalable 3′ mRNA-seq workflow. - Time-course and dose-response experiments
Expand experimental designs without the cost and complexity of conventional bulk RNA-seq. - Multi-species transcriptomics
Support RNA-seq projects across eukaryotic samples, including mammalian, plant, insect, and fish RNA. - Core facility / RNA-seq service provider workflows
Process many user-submitted purified RNA samples with early multiplexing and simplified library preparation. - Cost-effective alternative to conventional bulk RNA-seq
Generate gene-level expression data when isoform, splicing, or fusion analysis is not required.
1. MERCURIUS™ BRB-seq Detects Comparable Numbers of Genes and Differentially Expressed Genes as Illumina TruSeq
Comparison of gene detection (left) and differential expression (right) between the same samples prepared with MERCURIUS™ BRB-seq or Illumina TruSeq. (Left) Both protocols detect equivalent numbers of genes across all expression thresholds at the same sequencing depth. (Right) Differential expression analysis yields comparable numbers of differentially expressed genes for both technologies. MERCURIUS™ BRB-seq achieves TruSeq-equivalent analytical performance at significantly higher throughput and lower cost per sample.
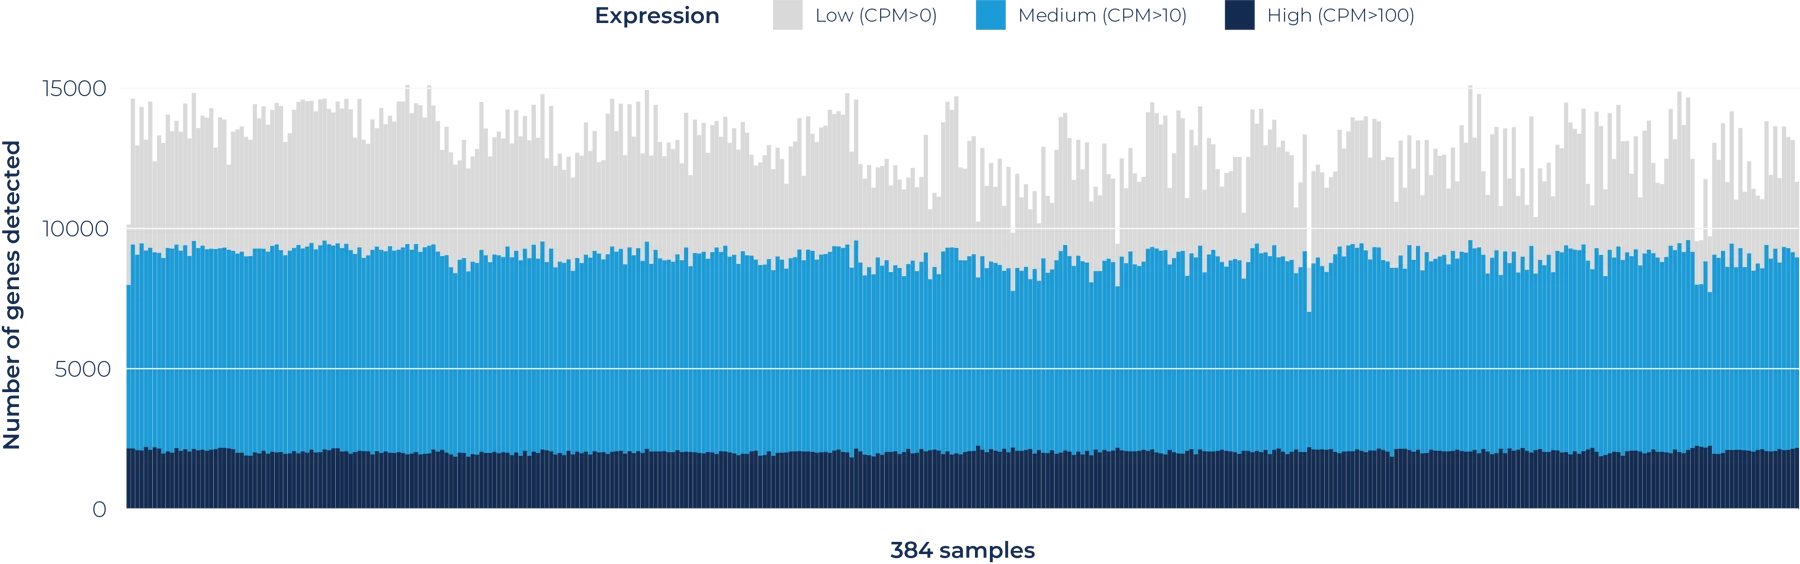
2. MERCURIUS™ BRB-seq Delivers Consistent, High-Sensitivity Gene Detection Across 384 Samples
Number of genes detected per sample across a 384-sample BRB-seq run, stratified by expression level. Across all 384 samples, an average of ~13,000 genes is detected when sequenced at a depth of 1.5M reads/sample. The uniformity of gene detection across all samples demonstrates the reproducibility and scalability of MERCURIUS™ BRB-seq for high-throughput transcriptomic profiling.
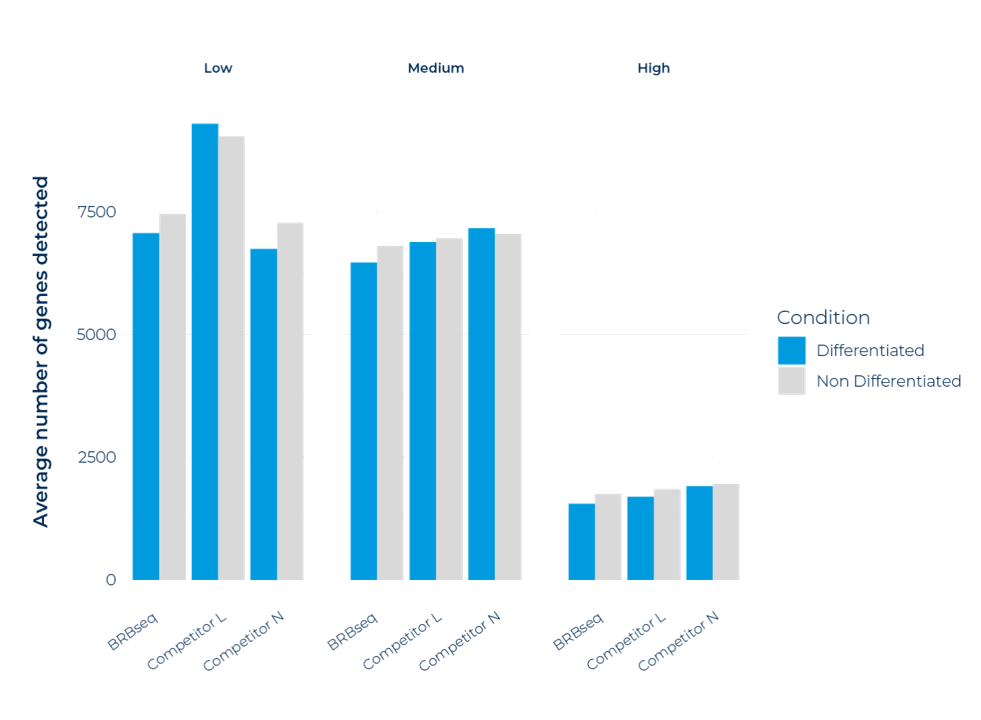
3. MERCURIUS™ BRB-seq Detects Comparable Numbers of Genes as Leading Commercial Platforms Across All Expression Levels
Average number of genes detected per expression category in non-differentiated (ND) and differentiated (D) adipose stromal population cells, comparing MERCURIUS™ BRB-seq against two commercial competitor kits. Genes are stratified into lowly expressed (0 < CPM < 10), mid-expressed (10 < CPM < 100), and highly expressed (CPM > 100) categories. All replicates were prepared from the same RNA sample and sequenced at a uniform depth of 3 million reads per sample. MERCURIUS™ BRB-seq performs comparably to both competitors across all expression levels and cell states.
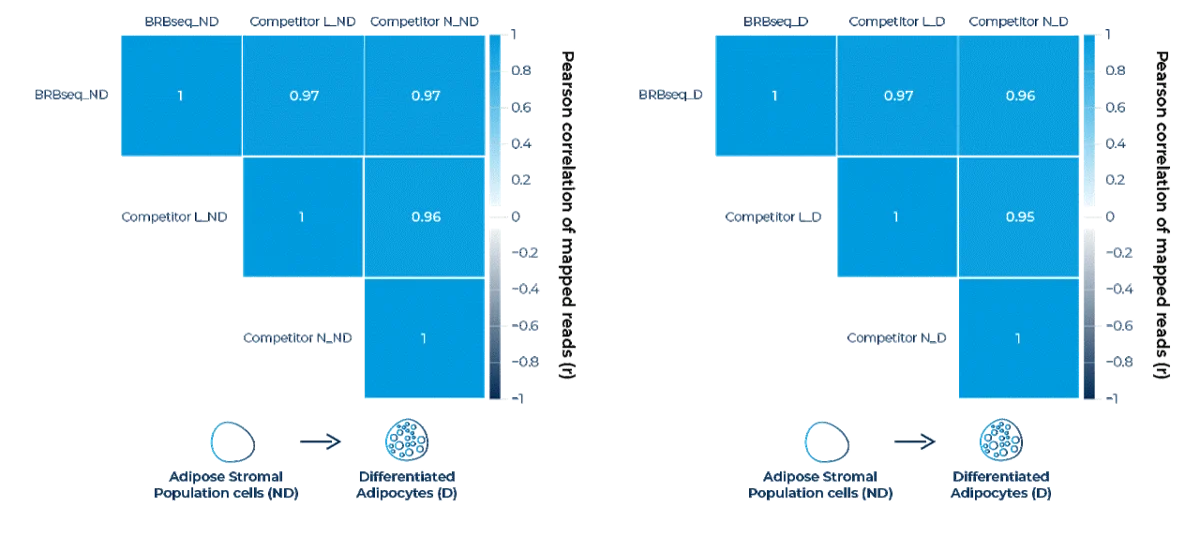
4. MERCURIUS™ BRB-seq has High Correlation with Leading Commercial Platforms in Both Undifferentiated and Differentiated Cell States
Transcriptome-wide Pearson correlation matrices of mapped reads comparing MERCURIUS™ BRB-seq against Competitor L and Competitor N in non-differentiated adipose stromal Population cells (ND, left) and differentiated adipocytes (D, right). MERCURIUS™ BRB-seq achieves Pearson correlation coefficients of r ≥ 0.97 against both competitors in both cell states, comparable to the inter-competitor correlation (r = 0.95–0.96), demonstrating that MERCURIUS™ BRB-seq produces highly concordant gene expression profiles regardless of biological condition.
5. MERCURIUS™ BRB-seq Identifies More Differentially Expressed Genes Than Competitor Platforms Across All Significance Thresholds
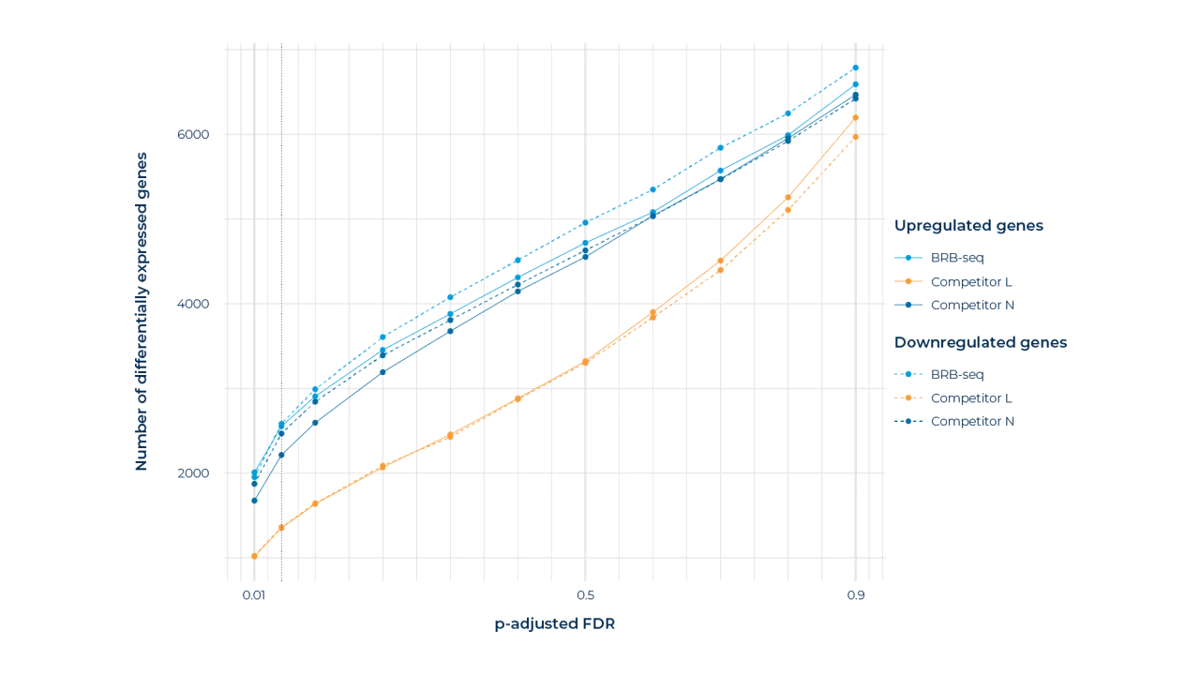
Number of up and downregulated differentially expressed genes (DEGs) detected by MERCURIUS™ BRB-seq, Competitor L, and Competitor N as a function of FDR-adjusted p-value threshold, comparing non-differentiated adipose stromal population cells to differentiated adipocytes at 3M reads/sample on the same initial RNA. MERCURIUS™ BRB-seq consistently identifies more DEGs than both competitors across the full range of significance thresholds, suggesting greater sensitivity for capturing the full transcriptional response to differentiation.
Sample Datasets
Human
96
10'000 reads
To have access to the deep-sequenced dataset (9.5M reads per sample) contact us.
79.9 MB
Mouse
96
10'000 reads
To have access to the deep-sequenced dataset (8.9M reads per sample) contact us.
78.6 MB
Cattle
54
10'000 reads
To have access to the deep-sequenced dataset (5.7M reads per sample) contact us.
28.4 MB
Wild Boar
54
10'000 reads
To have access to the deep-sequenced dataset (6.3M reads per sample) contact us.
27.7 MB
Bat
23
10'000 reads
To have access to the deep-sequenced dataset (9M reads per sample) contact us.
23.3 MB
Arabidopsis
96
10'000 reads
To have access to the deep-sequenced dataset (3M reads per sample) contact us.
47.9 MB
Spinach
96
10'000 reads
To have access to the deep-sequenced dataset (9M reads per sample) contact us.
83.9 MB
Drosophila
96
10'000 reads
To have access to the deep-sequenced dataset (3M reads per sample) contact us.
38.2 MB
Zebrafish
64
10'000 reads
To have access to the deep-sequenced dataset (4M reads per sample) contact us.
31.9 MB
Rainbow trout
16
10'000 reads
To have access to the deep-sequenced dataset (5.3M reads per sample) contact us.
8.76 MB
Medaka
96
10'000 reads
To have access to the deep-sequenced dataset (4.7M reads per sample) contact us.
50.6 MB
Product documentation
BRB-seq User Guide
Plant BRB-seq User Guide
Data analysis guide
Barcode files
Publications
- 3' BRB-seq, BRB-seq
Larissa Carvalho Costa, Christopher Gottschalk, Davis M. Upchurch, Oscar P. Hurtado-Gonzales, Ben N. Mansfeld, Alan Yocca, Lauren Whitt, Cheryl Vann, Gennaro Fazio
- 3' BRB-seq, BRB-seq
Stéphanie Boder‐Pasche, Mustafa Demir, Sarah Heub, Manon Garzuel, Réal Ischer, Daniel Migliozzi, Siegfried Graf, Noa Schmid, H. Baris Atakan, Daria Gudkova, Daniel Alpern, Riccardo Dainese, Bart Deplancke, Gilles Weder
- 3' BRB-seq, BRB-seq
Maxine Leonardi, Yves Paychère, Felix Naef.
Application
Equipment compatibility
Species compatibility
Available formats
Shipping conditions
Storage conditions
How many pools can I prepare with one kit?
Each BRB-seq kit contains reagents (including four pairs of Unique Dual Indexing adapters) sufficient for the complete library preparation process for four different BRB-seq pools.
To note, the total number of RNA samples that can be processed with one kit does not exceed the kit specifications; for instance, a 96-sample kit can be used to prepare up to 96 samples distributed across up to four different libraries.
What are the requirements for the RNA samples?
The recommended range of RNA amount for each sample is 50-1000 ng. Normally, the more RNA, the better.
The minimum recommended RIN number is 6 and the A260/230 ratio (Nanodrop) should be in the 1.5-2.2 range.
How does the bioinformatic analysis differ as compared to standard RNA-seq?
The only difference between BRB-seq and standard RNA-seq data analysis is the demultiplexing step, which is used to assign sequencing reads to their sample of origin based on the BRB-seq barcode sequence.
For a thorough description of BRB-seq data processing, please refer to the BRB-seq kit data analysis user guide.
What is the recommended sequencing depth for each RNA smaple?
One of the key advantages of BRB-seq is that it does not only save reagents and cost in the library preparation stage, but also in the sequencing one.
As opposed to standard RNA-seq, where 20M-30M reads per sample are required, we normally recommend to sequence BRB-seq libraries at a depth of 4M-5M reads per sample, which is normally enough to detect the vast majority of expressed genes.
How do I identify which barcode set I should use to demultiplex my data?
The barcode set for your kit is conveniently located on the kit label. Please refer to the label for accurate identification.
For optimal compatibility, ensure that you use the appropriate plate format (e.g., for kits designed for 96 reactions, the 96 well-plate format should be used). This ensures accurate and efficient processing of your samples. If you have any further questions or concerns, please contact our support team for assistance by email or using our live chat tool.
Ask your question:
Kit name
Catalog number
pairs
MERCURIUS™ BRB-seq library prep kit (96 preps)
all eukaryotic species
MERCURIUS™ BRB-seq library prep kit (4x96 preps)
all eukaryotic species
MERCURIUS™ BRB-seq library prep kit (384 preps)
all eukaryotic species
MERCURIUS™ BRB-seq library prep kit (4x384 preps)
all eukaryotic species
* Contact us to inquire about compatibility with other species.
Accessories
Product
MERCURIUS™ MQ.UDI Expansion module
MERCURIUS™ X-Leap-compatible MQ.UDI Expansion module
MERCURIUS™ X-Leap-compatible MQ.UDI.X Expansion module
MERCURIUS™ Standard Post-Pooling Preparation Module (4 libraries)
Ordering tip
Each kit includes 4 UDI pairs. Add the expansion module if you need more unique indexes (total 16 UDI pairs available).
Relevant blogs
August 25, 2025
Determining the most suitable transcriptomic technology to drive your large-scale compound screen, clinical study, or to assess a panel of genetic perturbations can be a…
August 25, 2025
‘High-throughput’ in sequencing refers to the amount of DNA molecules read at the same time. Technologies are now capable of sequencing many fragments of DNA…
May 9, 2025
With a growing number of published 3’ mRNA-seq methods now available, researchers have more choices than ever for high-throughput and cost-effective transcriptomic screening. While broadly…
May 6, 2025
In this post, we will see briefly how to perform downstream analysis for RNA-seq data.
…