How to Generate AI-Ready Perturbation Datasets for Reproducible Mechanism-of-Action and Toxicity Prediction with MERCURIUS™ 1536 DRUG-seq
AI models trained to predict compound mechanism of action or toxicity are only as good as the perturbation datasets they learn from. These perturbation datasets must be standardized, reproducible, and large enough for AI-scale drug discovery. This is strategically crucial as proprietary perturbation data, not model architecture, is increasingly the competitive moat for AI-native biopharma, and standardized data generation is what makes rapid iteration possible within a lab-in-the-loop workflow.
Yet, most screening-scale compound-perturbation profiling methods force a trade-off. Probe-based gene expression profiling captures only a fraction of the transcriptome, and morphological profiling methods like Cell Painting detect phenotypic changes without revealing which gene expression pathway or program drove it.
MERCURIUS™ 1536 DRUG-seq closes that gap. In a 33-compound perturbation screen across two independently processed 1536-well plates, the assay generated transcriptome-wide data with the reproducibility and gene-level resolution to correctly cluster compounds by known mechanism, detect activation across 18 toxicity and 14 mechanism-of-action (MoA) pathways, and capture early apoptotic transcriptional signals before conventional viability assays could.
What the MERCURIUS™ 1536 DRUG-seq Compound-Perturbation Data Shows
Why this matters for your model
A dataset that clusters compounds correctly by MoA, distinguishes mechanistically related compounds at the gene level, and catches toxicity signal earlier than apical endpoints gives a foundation model richer, more informative data points per experiment. This makes the difference between a dataset that’s merely large and one that’s rich in broad biological information for training MoA classifiers and toxicity predictors or experimentally evaluating AI-generated predictions at scale.
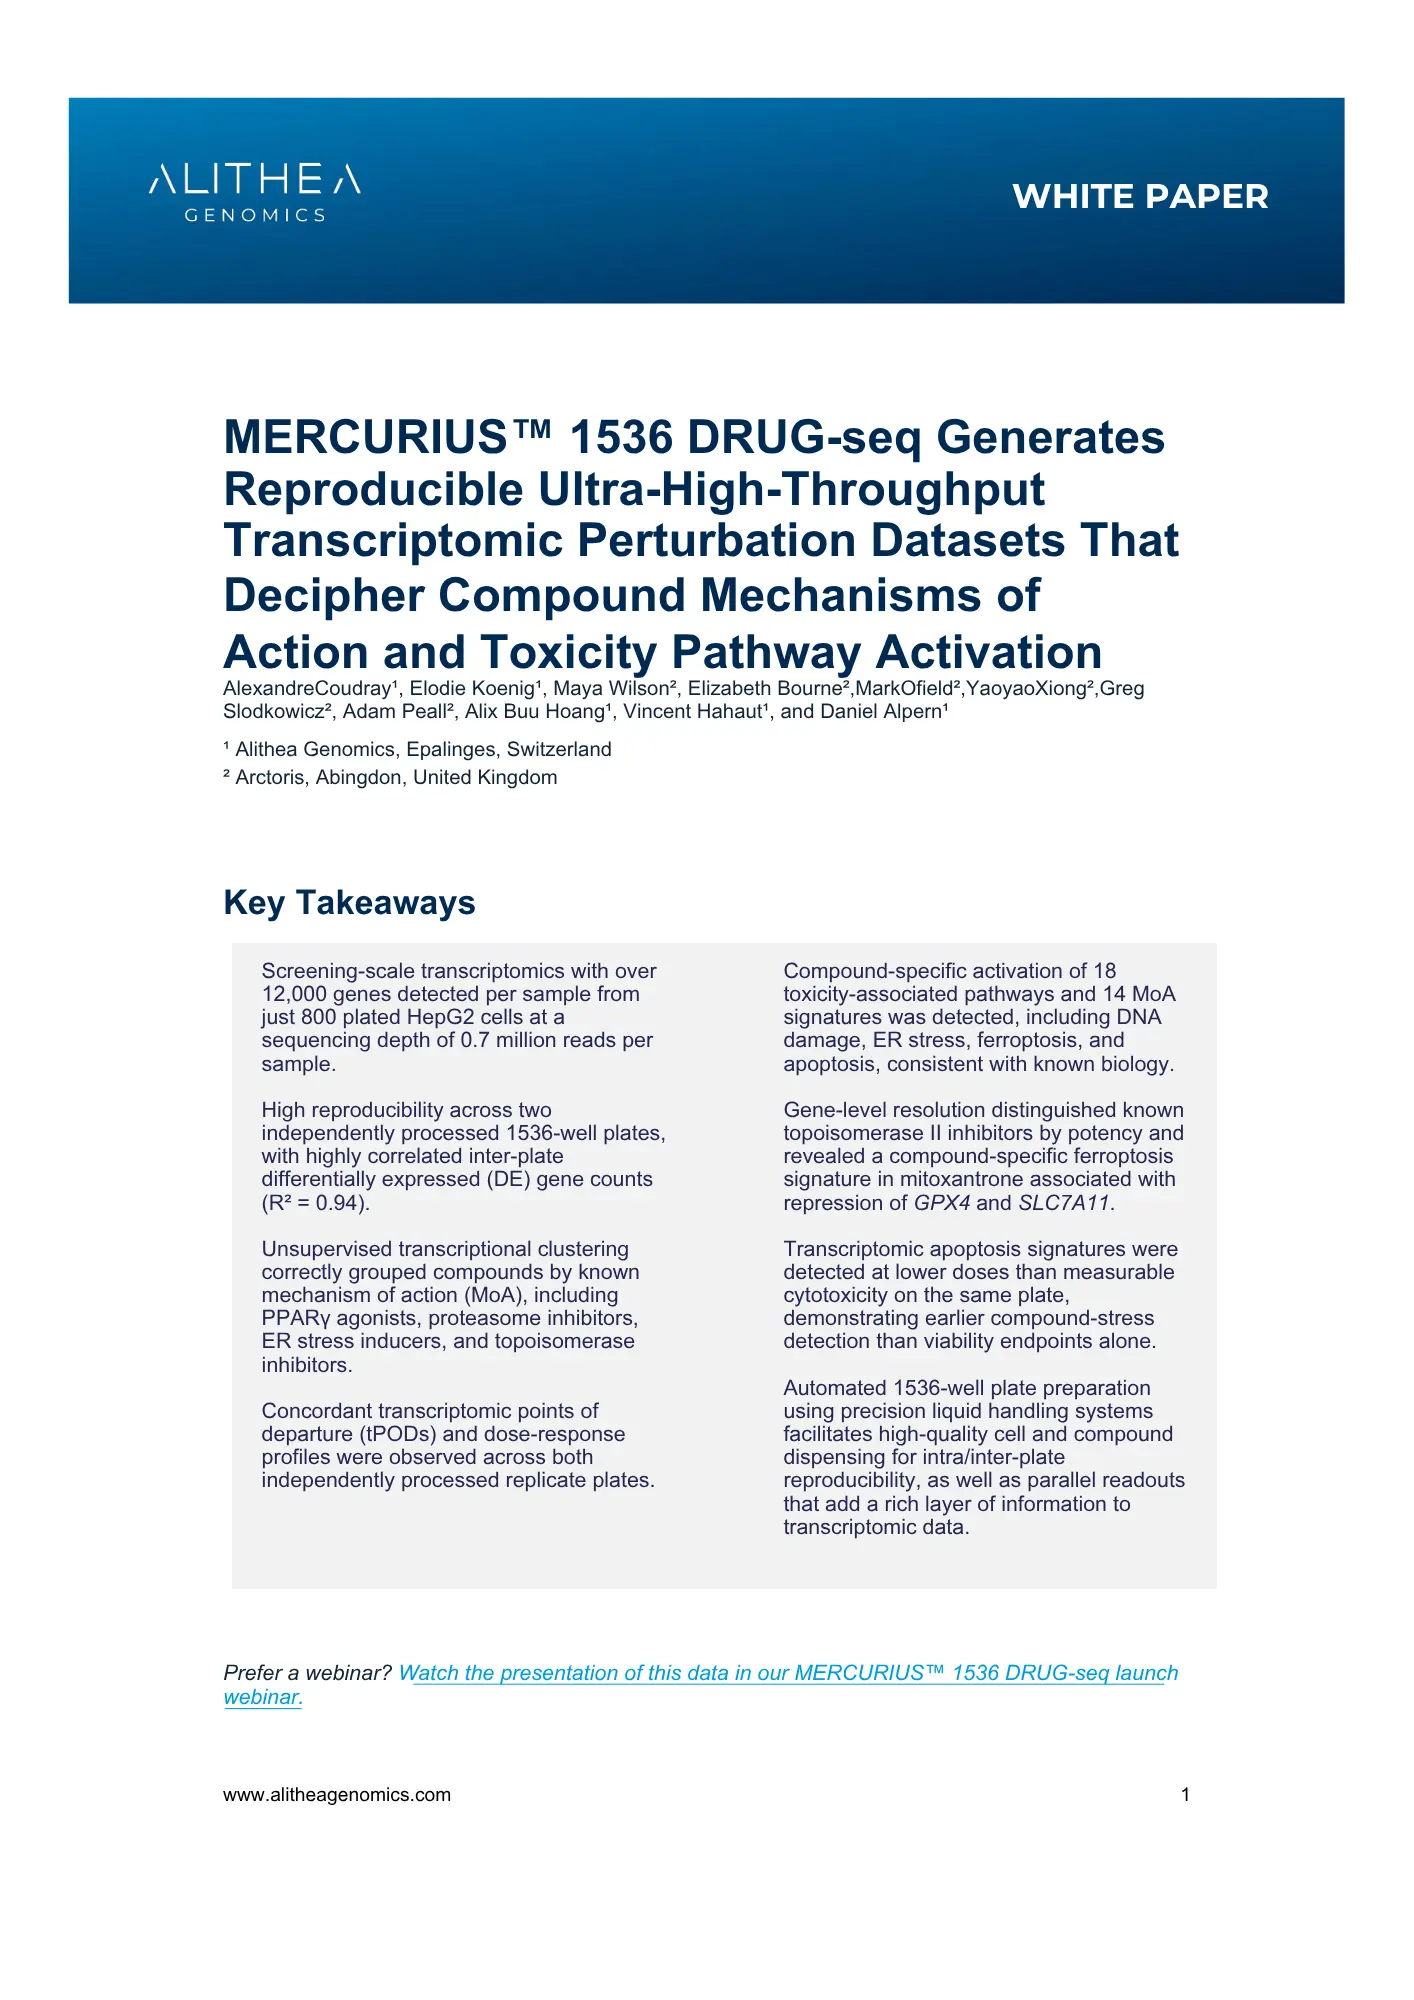
Authors: Alexandre Coudray¹, Elodie Koenig¹, Maya Wilson², Elizabeth Bourne², Mark Ofield², Yaoyao Xiong², Greg Slodkowicz², Adam Peall², Alix Buu Hoang¹, Vincent Hahaut¹, and Daniel Alpern¹
Tell us about your project and we will help you find the right approach.